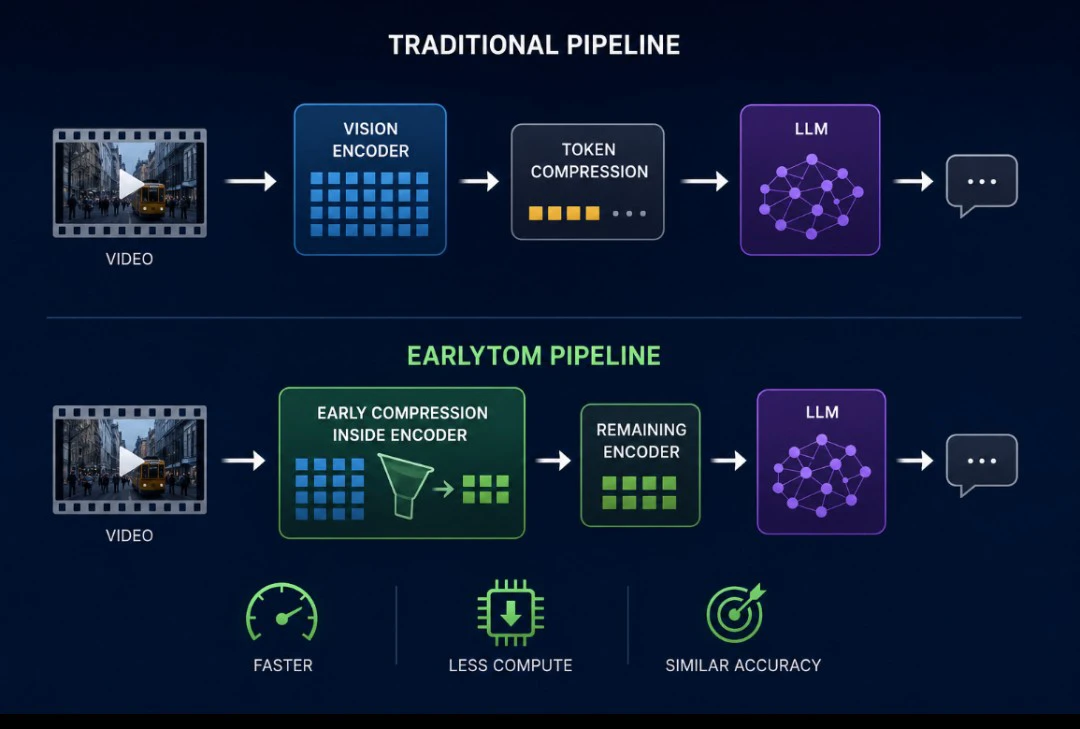
A new AI research paper titled EarlyTom proposes early-stage token compression for Video-LLMs, reducing computation costs while significantly improving inference speed.